From 62de9383d35501d278da68e262aefa144f7aa758 Mon Sep 17 00:00:00 2001
From: Zhibo Lin <147509942+LE0-Lin@users.noreply.github.com>
Date: Wed, 4 Nov 2026 23:06:49 +0800
Subject: [PATCH] docs: focus project introduction on instruction change review
---
CHANGELOG.md | 4 +
README.md | 710 ++++++++----------------------------------
README.simplified.md | 42 ++-
README.traditional.md | 42 ++-
docs/README.md | 1 +
docs/reference.md | 443 ++++++++++++++++++++++++++
docs/translations.md | 11 +-
7 files changed, 666 insertions(+), 587 deletions(-)
create mode 100644 docs/reference.md
diff --git a/CHANGELOG.md b/CHANGELOG.md
index fb868fc..580086d 100644
--- a/CHANGELOG.md
+++ b/CHANGELOG.md
@@ -2,6 +2,10 @@
## Unreleased
+### Documentation
+
+- Refocus the English/Simplified/Traditional project overviews on instruction-change review and baseline-governed checks. Separate published v0.24.0 from unreleased Cursor analysis, add a concrete attachment-loss example, and move detailed policy/CLI/integration material into a reference page while retaining the visual demos. Point to the current pinned-corpus status: five scans and an expected Reaparr source rejection with no score, rather than presenting its historic A 100 as current. Runtime rules, artifacts and frozen evidence are unchanged.
+
### Added
- Unreleased `scope compare` and Git-backed `scope diff` for the same declared Cursor file context: file lifecycle, trigger matches and aggregated exact-directive availability, with original line evidence and captured source hashes. Optional caller-owned flags gate recognized active losses and unknowns separately; active duplicate/renamed sources and remaining multi-file triggers retain availability. Includes four runnable synthetic examples and source-build CI guidance. This is bounded attachment/recognition analysis, not general semantic impact or runtime enforcement; normal scoring, policy schema, published packages and Action refs are unchanged.
diff --git a/README.md b/README.md
index 2ab44a1..7fffd11 100644
--- a/README.md
+++ b/README.md
@@ -3,14 +3,10 @@
English | [简体中文](https://github.com/LE0-Lin/AgentConfigScore/blob/main/README.simplified.md) | [繁體中文](https://github.com/LE0-Lin/AgentConfigScore/blob/main/README.traditional.md)
-  +
-Codecov for AI coding-agent instructions.
-
-
- Stop pull requests from quietly making AGENTS.md, CLAUDE.md, Cursor, Copilot and Gemini instructions worse.
-
+Catch known regressions in coding-agent instructions before merging.
 @@ -21,102 +17,104 @@ English | [简体中文](https://github.com/LE0-Lin/AgentConfigScore/blob/main/R

+AgentConfigScore runs local, deterministic checks on `AGENTS.md`, `CLAUDE.md`,
+Cursor, Copilot and Gemini instructions. It compares a change with its baseline,
+reports rule-defined regressions, and uses reviewed baseline policies for CI
+decisions. No model API or runtime dependencies are needed.
+
- 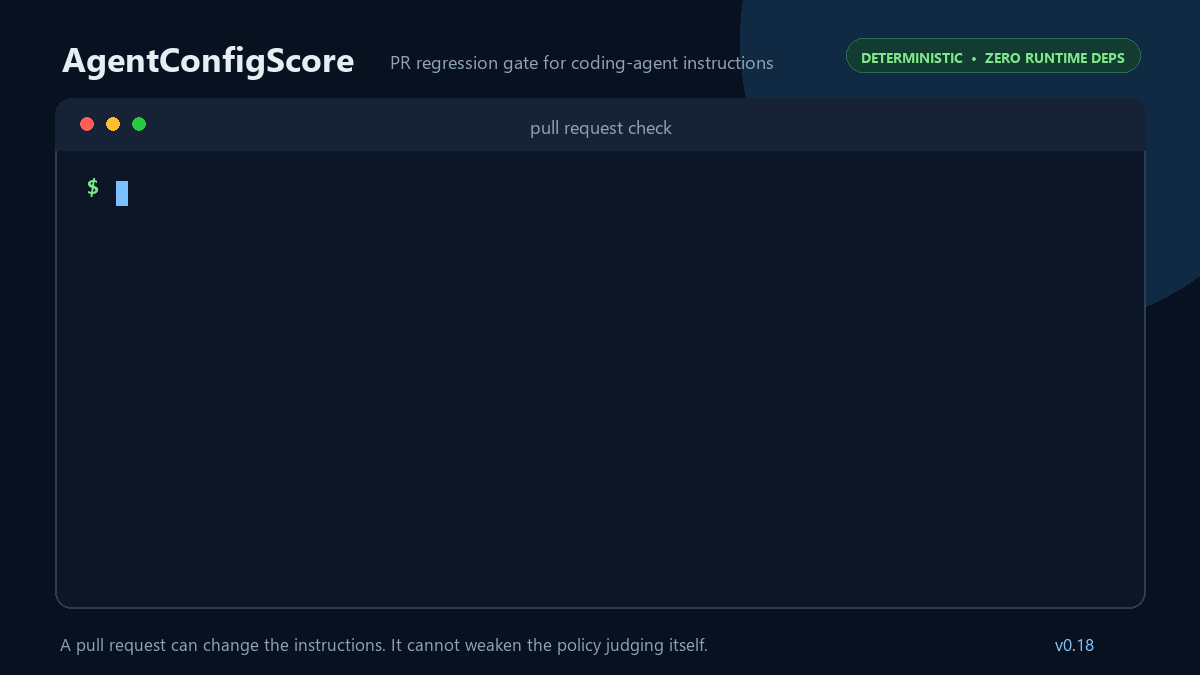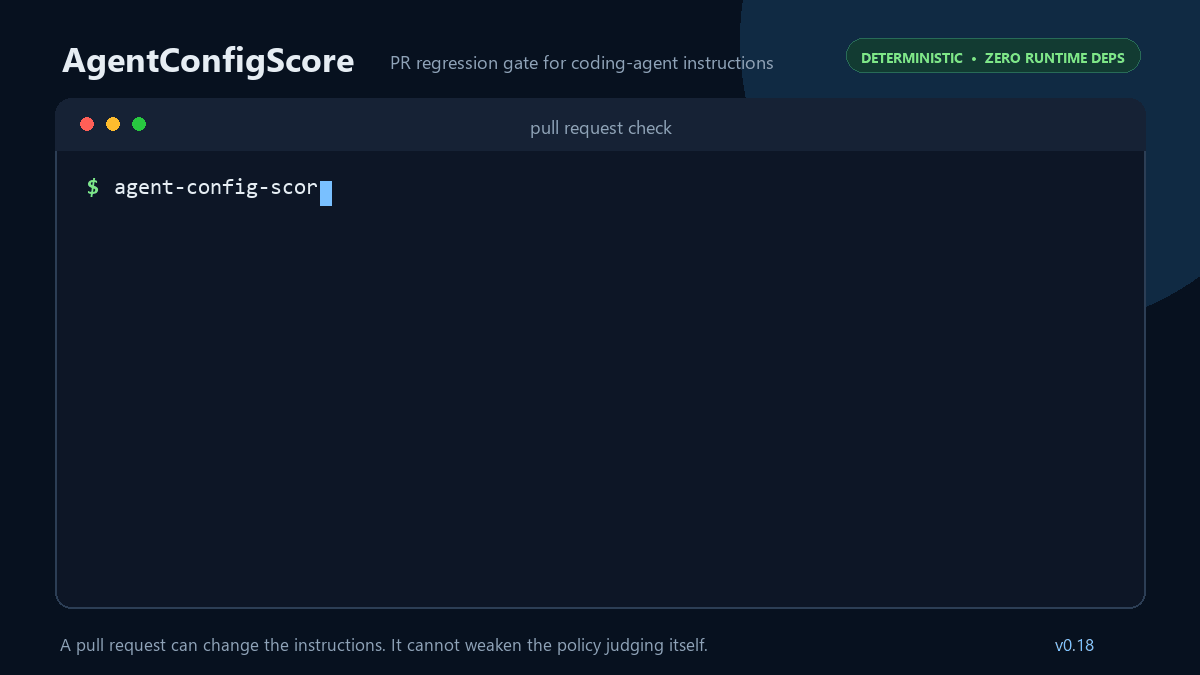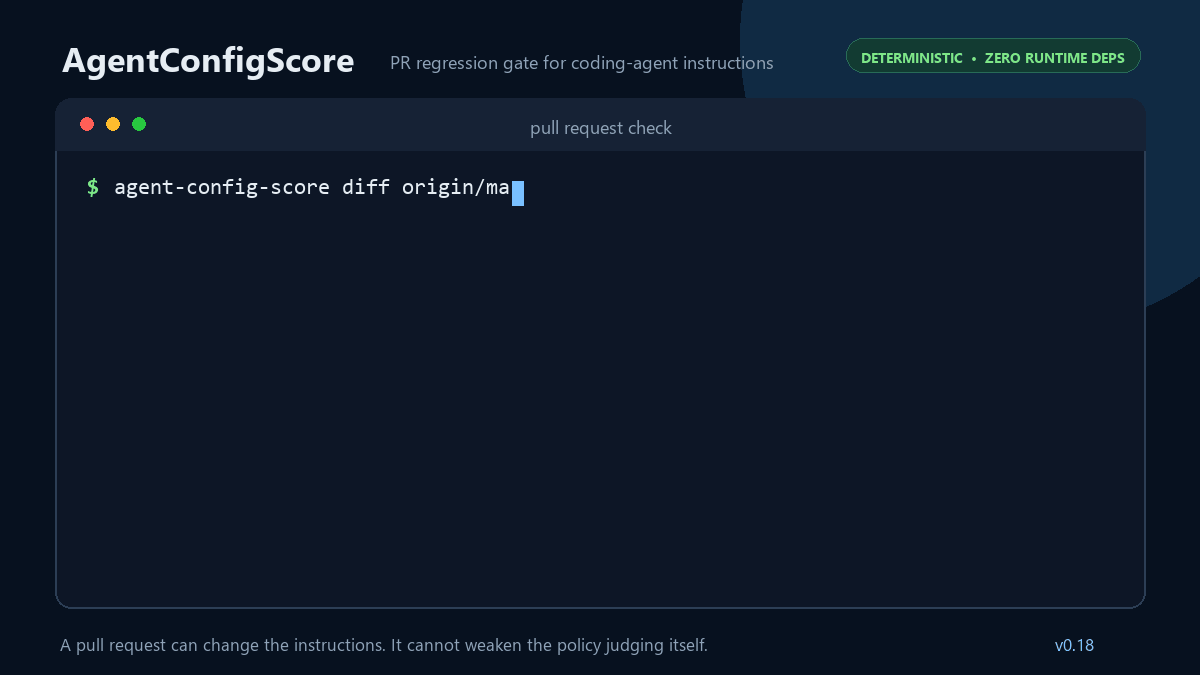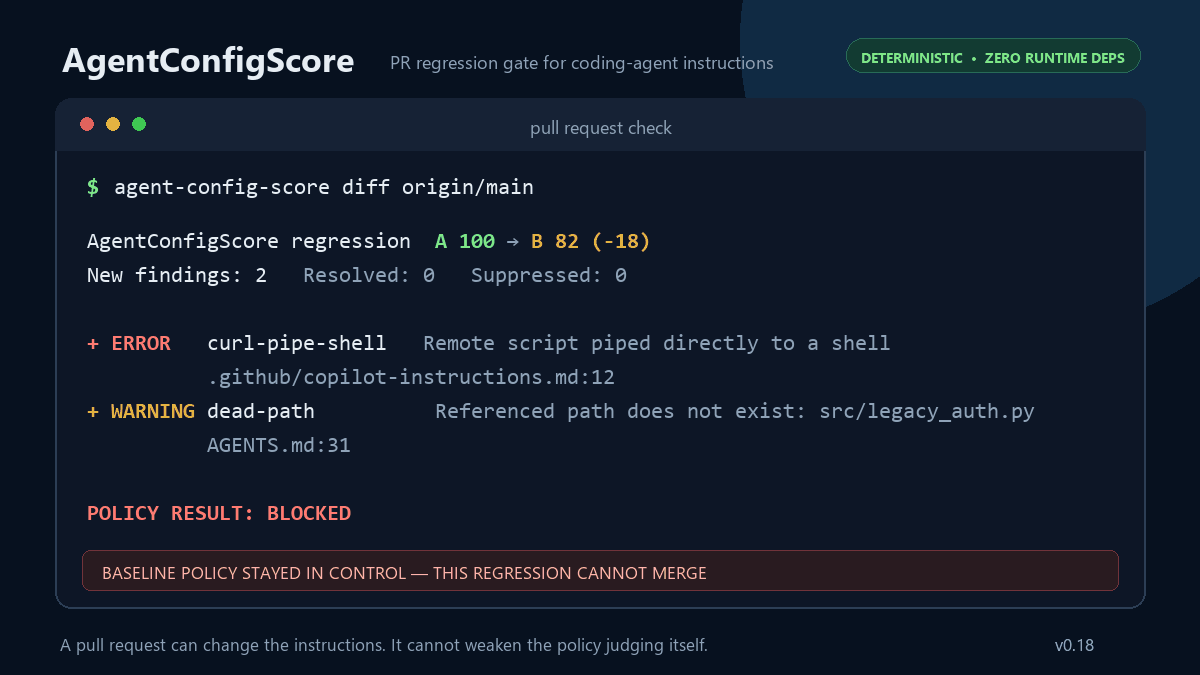 +
-AgentConfigScore is a deterministic regression gate for coding-agent configuration. It compares a change with its baseline and answers one CI-friendly question:
-
-> **Did this change make our agent instructions worse?**
-
-It is regression-first rather than perfection-first: an existing repository can start at 72/100 and adopt the gate immediately. A pull request that stays at 72 can pass; one that drops to 65 can fail.
+**A 100 means no active deterministic rule matched.** It does not certify
+instruction usefulness, semantic correctness or safety.
+[Read the score contract and limitations.](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/limitations.md)
-> [!IMPORTANT]
-> **A 100 means no active deterministic rule matched—not that the instructions are semantically perfect.** AgentConfigScore is a focused linter, not an AI judge. See the public [score contract and known blind spots](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/limitations.md).
+## What it helps you review
-| What usually goes wrong | What the gate does |
+| Change | Review evidence |
|---|---|
-| A pull request weakens its own quality threshold | Uses the baseline branch's policy to judge the change |
-| A new instruction contradicts or duplicates existing guidance | Reports deterministic, line-addressable findings |
-| A pull request deletes an instruction file or reverses an exact directive | Emits a regression-only error even when ordinary score arithmetic would miss it |
-| An exception becomes a permanent silent ignore | Requires a reason and expiry, then preserves an audit trail |
-| A scanner update becomes noisy on real projects | Replays a pinned, manually reviewed [real-repository benchmark](https://github.com/LE0-Lin/AgentConfigScore/blob/v0/benchmarks/README.md) |
+| Add a recognized unsafe command, exposed credential or broken path | Rule ID, explanation and source location where available |
+| Delete an instruction file or reverse an exact directive | A regression-only finding, even when both numeric scores stay the same |
+| Lower the candidate's threshold or add its own exception | The normal comparison still uses baseline policy and suppressions; trusted caller overrides are explicit |
+| Accept a known exception | A reason, expiry and visible audit record |
-
- 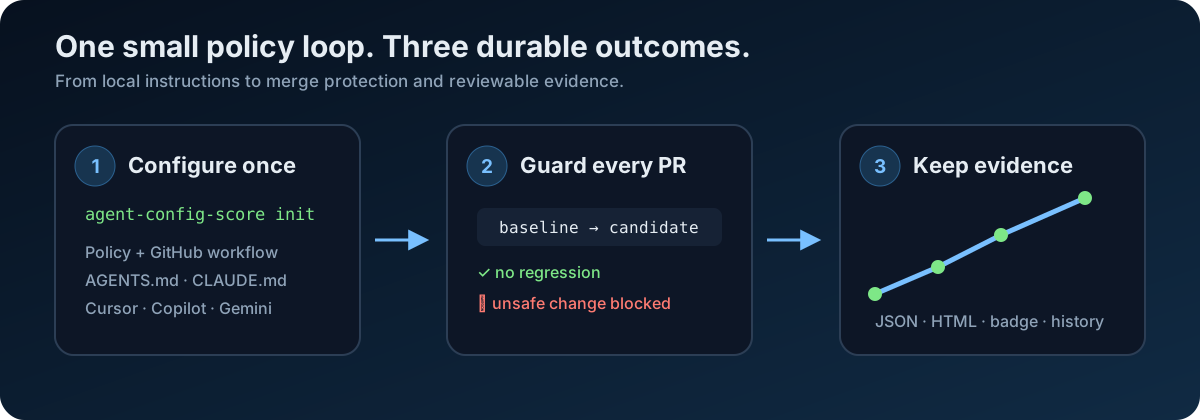 -
-
-See the complete [visual tour](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/visual-tour.md) for setup, regression, and history demos.
+Existing repositories can adopt the gate without first reaching 100.
+`init` enables new-error blocking and no score decrease; a passing comparison
+means no regression under the selected rules and policy.
-## Get running
+## Quick start
-New here? The [user guide](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/user-guide.md) covers setup, pass/fail behavior,
-exit codes and troubleshooting. The [documentation index](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/README.md)
-separates everyday usage from research and benchmark material.
+Run inside your repository with a supported instruction file:
```bash
-python -m pip install agent-config-score
+python -m pip install --upgrade agent-config-score
+agent-config-score --version
agent-config-score init
+agent-config-score doctor
+agent-config-score diff
```
-
- 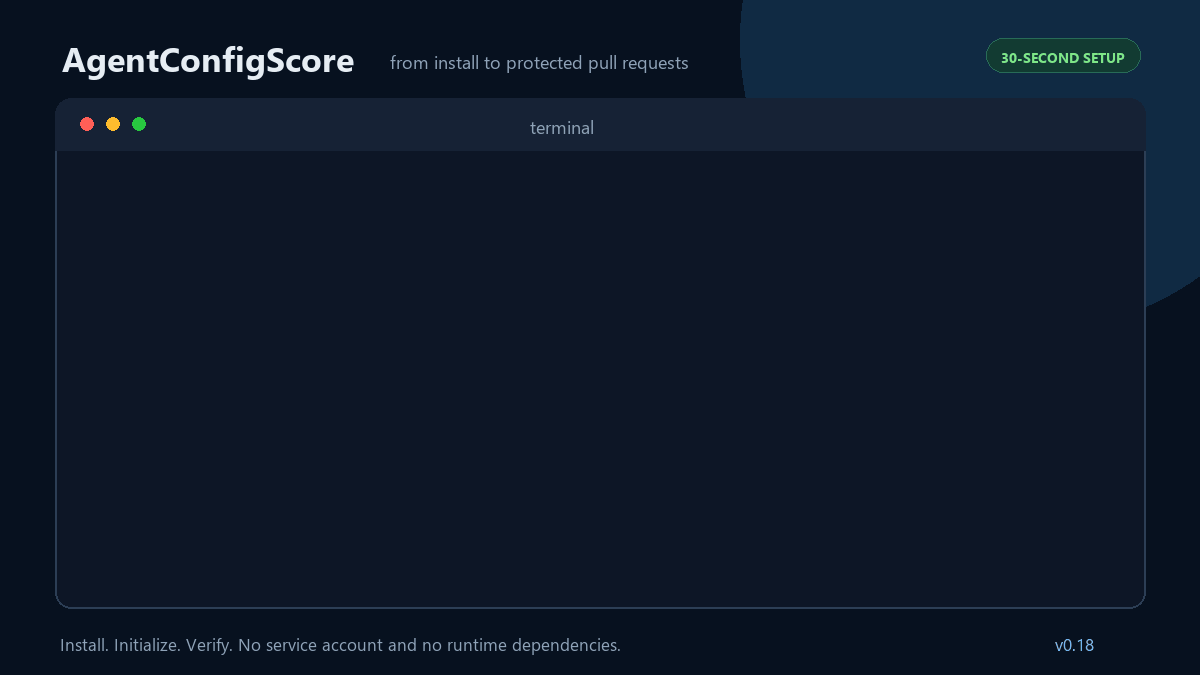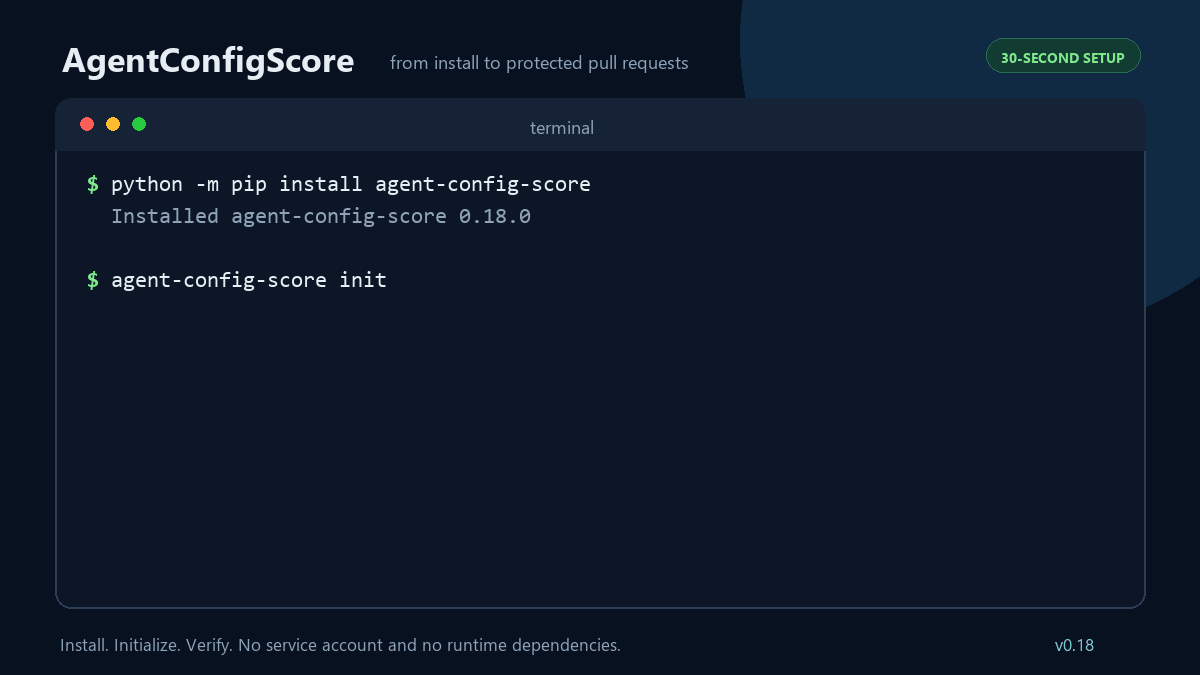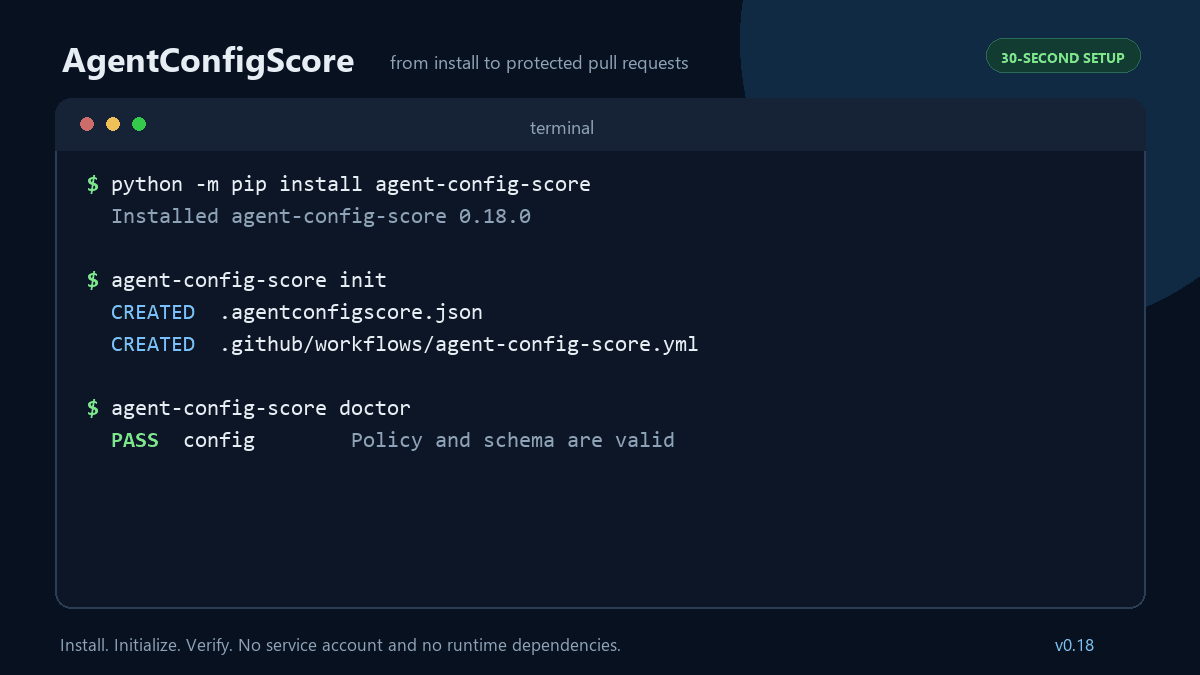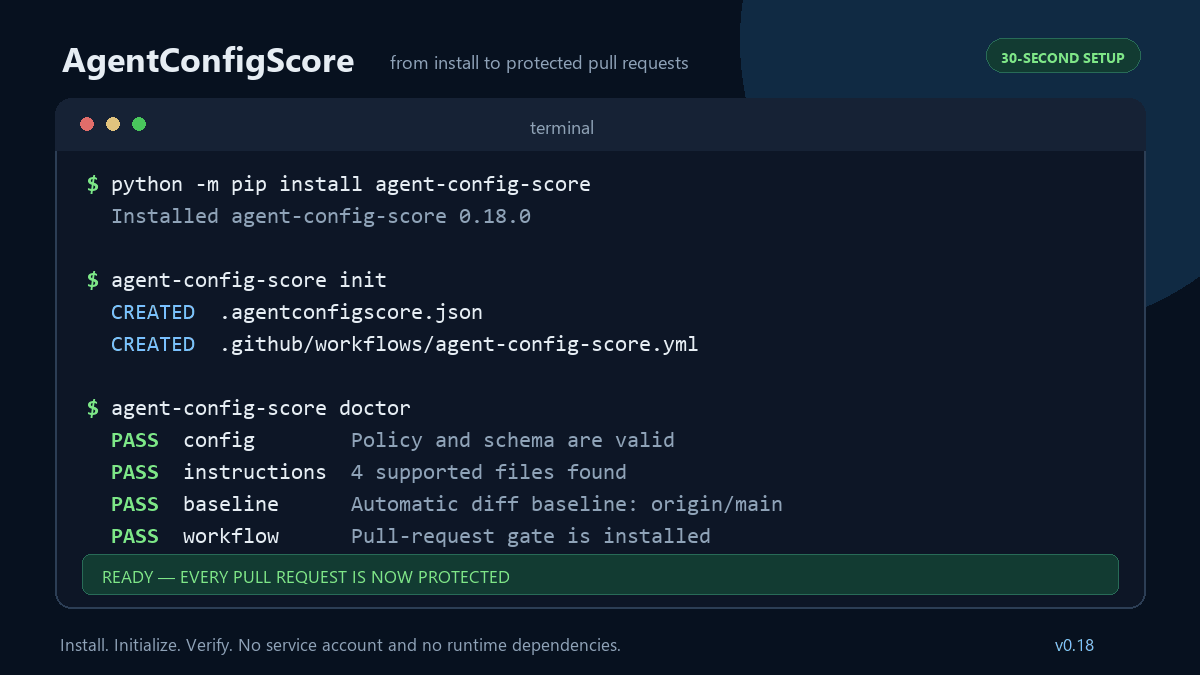 -
+Review and commit the generated `.agentconfigscore.json` and
+`.github/workflows/agent-config-score.yml`. `init` does not write your agent
+instructions or overwrite conflicting setup files by default. `acs` and
+`python -m agent_config_score` are alternative entrypoints.
-To test the latest stable pre-1.0 source directly from GitHub instead:
+`diff` includes uncommitted changes. It detects a conservative local baseline
+without fetching; use `agent-config-score diff origin/main` when you want an
+explicit ref. The [user guide](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/user-guide.md)
+covers setup, exits and troubleshooting.
-```bash
-python -m pip install "git+https://github.com/LE0-Lin/AgentConfigScore.git@v0"
-```
+## Release and source status
-`init` safely creates:
+| Version | Available capability |
+|---|---|
+| Published v0.24.0 | Local lint, baseline-governed regression gates, auditable exceptions, reports and opt-in deletion-safeguard review |
+| Unreleased source on `main` | Cursor file-context activation and before/after attachment review, plus the fixes listed in the changelog |
-- `.agentconfigscore.json` — version-controlled policy, suppressions, and editor schema annotation
-- `.github/workflows/agent-config-score.yml` — pull-request regression gate
+The PyPI package and rolling `v0` Action do **not** contain the unreleased
+Cursor commands. See [v0.24.0 release notes](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/releases/v0.24.0.md)
+and the [changelog](https://github.com/LE0-Lin/AgentConfigScore/blob/main/CHANGELOG.md)
+before choosing an installation or Action revision.
-Review and commit those files. Pull requests are then checked automatically.
+## Cursor attachment changes — unreleased source
-Validate the integration and run the same regression check locally before pushing:
+An instruction can stop attaching even when its words and score stay unchanged.
+For a declared API-only task:
-```bash
-agent-config-score doctor
-agent-config-score diff
-```
+| Property | Baseline | Candidate |
+|---|---|---|
+| Instruction | Never delete files without approval. | Same text |
+| Cursor glob | `src/**` | `src/web/**` |
+| Declared task file | `src/api/service.py` | Same path |
+| Ordinary scan score | 100 | 100 |
+| Predicted automatic attachment | Active | Inactive |
-`diff` auto-detects a safe local default-branch baseline when possible. You can still pass an explicit ref such as `origin/main` whenever you want full control.
-
-Initialization is conservative: every target is preflighted before anything is written, conflicting files are never overwritten by default, and rerunning against matching generated files is idempotent.
+From a source checkout, run the synthetic example:
```bash
-agent-config-score init --dry-run # preview without writing
-agent-config-score init --no-workflow # config only
-agent-config-score init --force # intentionally replace conflicting generated files
+python -m pip install -e .
+agent-config-score scope compare \
+ examples/cursor-scope-impact/base examples/cursor-scope-impact/narrowed \
+ --target src/api/service.py --fail-on-lost-directives --fail-on-unknown
```
-`v0` is the rolling stable ref for the current pre-1.0 series.
+Expected exit **1**: review is requested for the lost recognized active directive.
+Reports identify metadata and directive source lines. Another active copy or a
+remaining multi-file trigger can retain availability; manual/model-selected
+loading and unsupported inputs remain unknown.
-## Copy-ready templates
+The comparison models the **same declared file context** on both sides. It does
+not observe an agent run or prove semantic equivalence. Comparisons are advisory
+unless flags opt into the review gate; these flags are caller-owned and do not
+extend the existing baseline score-policy schema.
-v0.24.0+ provides an optional [deletion-safeguard review and
-completion workflow](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/guardrail-suggestions.md):
-preview a selected file with `agent-config-score guardrails . --file AGENTS.md`,
-review the proposed addition, then explicitly confirm it before an append.
-This is unscored advice, not proof of danger or safety; it does not change the
-default regression gate.
-
-Start with a conservative template, then replace generic guidance with your
-repository's real commands, architecture, and ownership boundaries:
-
-- [Cursor Project Rule](https://github.com/LE0-Lin/AgentConfigScore/blob/main/examples/cursor/.cursor/rules/project.mdc)
-- [GitHub Copilot instructions](https://github.com/LE0-Lin/AgentConfigScore/blob/main/examples/copilot/.github/copilot-instructions.md)
-- [Gemini CLI context](https://github.com/LE0-Lin/AgentConfigScore/blob/main/examples/gemini/GEMINI.md)
-- [Claude Code instructions](https://github.com/LE0-Lin/AgentConfigScore/blob/main/examples/claude-code/CLAUDE.md)
-
-The [examples guide](https://github.com/LE0-Lin/AgentConfigScore/tree/main/examples) includes exact target paths and copy commands.
+Try the [four controls](https://github.com/LE0-Lin/AgentConfigScore/blob/main/examples/cursor-scope-impact/README.md),
+or use [`scope diff` with a local Git baseline](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/cursor-scope-impact.md).
## Repository policy + editor validation
-A generated config looks like this:
+The generated policy enables regression checks:
```json
{
@@ -129,525 +127,77 @@ A generated config looks like this:
}
```
-The `$schema` annotation enables live validation and completion in editors that support JSON Schema. It can catch misspelled policy keys, wrong value types, unknown suppression rule IDs, missing suppression fields, and malformed path scopes before CI runs.
-
-The schema is Draft 2020-12 and lives at `schema/agentconfigscore.schema.json`. AgentConfigScore's tests verify that its suppression rule enum stays exactly aligned with the stable Rule Catalog, so editor hints cannot silently drift away from scanner behavior.
-
-Unreleased source builds additionally reject duplicate JSON member names at any
-depth, even if the values match or a name uses JSON escapes. A repeated threshold
-is a configuration error, not "last value wins." `NaN`/`Infinity` constants and a
-Boolean format `version` are rejected too. Keep one reviewed value per field;
-do not rely on editor schema validation to detect duplicate names. See
-[configuration failure behavior](docs/doctor.md#configuration-decoding). These
-changes are not in the published v0.24.0 artifacts.
-
-Policy fields:
-
-| Key | Default | Meaning |
-|---|---:|---|
-| `max_drop` | `0` | Maximum score decrease allowed by `diff` / `compare` |
-| `fail_on_new_errors` | `false` in the CLI; `true` in the Action when no policy file exists | Fail on newly introduced active error findings |
-| `fail_under` | unset | Optional absolute score floor for a normal scan |
-
-An absolute floor is optional:
-
-```json
-{
- "$schema": "https://raw.githubusercontent.com/LE0-Lin/AgentConfigScore/v0/schema/agentconfigscore.schema.json",
- "version": 1,
- "policy": {
- "max_drop": 0,
- "fail_on_new_errors": true,
- "fail_under": 90
- }
-}
-```
-
-### Why the baseline policy governs a PR
-
-A pull request must not be able to weaken the gate that reviews it.
-
-For `diff`, `compare`, and the reusable GitHub Action, AgentConfigScore uses the **baseline** policy to decide pass/fail. The candidate config is still parsed and validated, but new thresholds only become active after that config is reviewed, merged, and becomes a later baseline.
-
-A candidate changing `max_drop` to `100` therefore cannot use that weaker value to pass itself. Explicit CLI or Action inputs remain available as trusted invocation-time overrides.
+Normal `diff` / `compare` and the reusable Action use the baseline's policy,
+so candidate threshold edits cannot approve that same change. The candidate
+config is still validated. Explicit CLI/Action overrides belong to the trusted
+caller. [Policy defaults, schema and overrides](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/reference.md#repository-policy--editor-validation).
## Auditable exceptions
-Sometimes a finding is understood and intentionally accepted. AgentConfigScore supports suppressions, but does not treat them as a permanent ignore list.
-
-Every suppression must name a stable rule, explain the exception, and expire:
-
-```json
-{
- "$schema": "https://raw.githubusercontent.com/LE0-Lin/AgentConfigScore/v0/schema/agentconfigscore.schema.json",
- "version": 1,
- "policy": {
- "max_drop": 0,
- "fail_on_new_errors": true
- },
- "suppressions": [
- {
- "rule": "dead-path",
- "reason": "Generated docs reference paths that only exist after deployment.",
- "expires": "2026-12-31",
- "paths": ["docs/**"]
- }
- ]
-}
-```
-
-Rules for suppressions:
-
-- `rule` must be a known stable AgentConfigScore rule ID
-- `reason` must be non-empty and is limited to 500 characters
-- `expires` must be `YYYY-MM-DD`
-- an expired suppression is a configuration error; remove it or explicitly renew it
-- `paths` is optional and accepts unique instruction-file glob patterns
-- path-scoped suppressions never hide repository-level findings such as cross-file contradiction
-- duplicate rule/path scopes are rejected
-
-Suppressions are **not silent**. A matching finding stops contributing to score and regression decisions, but remains visible in the `suppressed_findings` audit trail in JSON and is shown with its reason and expiry in terminal, HTML, and Markdown output.
-
-Suppressions are baseline-governed too: a PR cannot add a suppression and use it to excuse a finding introduced by that same PR. The baseline suppression set is applied to both sides of a regression comparison.
-
-## Check locally before you push
-
-The common path is now zero-config:
-
-```bash
-agent-config-score doctor
-agent-config-score diff
-```
-
-`doctor` validates the repository integration. `diff` compares the current working tree—including uncommitted changes—with a safe local default-branch baseline.
-
-When no `BASE_REF` is provided, AgentConfigScore detects a baseline conservatively in this order:
-
-1. locally configured `origin/HEAD`
-2. local `main`
-3. local `master`
-4. local `trunk`
-5. an upstream whose branch name itself is `main`, `master`, or `trunk`
-
-It deliberately does **not** use a feature-branch upstream such as `origin/my-feature` as the baseline, because doing so could hide committed changes relative to the real default branch.
-
-AgentConfigScore creates an isolated detached baseline worktree, compares it with your current repository, then removes the temporary worktree automatically. Automatic detection is fully offline and never runs `git fetch`.
-
-If no safe local baseline can be identified, pass one explicitly:
-
-```bash
-agent-config-score diff origin/main
-```
-
-If that ref is not available locally, fetch it yourself and retry. AgentConfigScore never fetches a missing ref behind your back.
-
-Trusted threshold overrides are explicit:
-
-```bash
-agent-config-score diff \
- --max-drop 3 \
- --no-fail-on-new-errors
-```
-
-You can run `diff` from any subdirectory inside the repository. Use `--path DIR` to point at another local repository.
-
-## What a failing PR looks like
-
-```text
-AgentConfigScore regression A 96 → B 84 (-12)
-New findings: 2 Resolved: 0 Suppressed: 0
-
-+ ERROR curl-pipe-shell Remote script piped directly to a shell
- .github/copilot-instructions.md:12
-+ WARNING dead-path Referenced path does not exist: src/legacy_auth.py
- AGENTS.md:31
-```
-
-**Live proof:** [PR #6](https://github.com/LE0-Lin/AgentConfigScore/pull/6) deliberately added an unsafe `curl | bash` instruction. AgentConfigScore changed the score from **A 100 → B 82 (-18)**, reported a new `curl-pipe-shell` error, failed the GitHub Actions job, and the PR was closed without merging.
-
-## Adversarial Benchmark v1
-
-The offline mutation benchmark expands reviewed fixtures across six instruction
-formats and separates current guarantees from open research challenges:
-
-| Tier | Result | Meaning |
-|---|---:|---|
-| Deterministic contract | 474/474 exact matches | Current rule behavior stayed reproducible |
-| Clean negative controls | 212/212 passed | No unexpected finding in controlled clean cases |
-| Open challenge set | 6/8 detected | Four danger surfaces, explicit false reporting, and bulk environment transfer are covered; two semantic cases remain unsolved |
-
-The contract suite reports 100% precision and recall only for its closed labeled
-fixtures—not for arbitrary repositories. See the [corpus, runner, methodology,
-and full report](https://github.com/LE0-Lin/AgentConfigScore/tree/main/benchmarks).
-
-The scanner shares a source-positioned document context between danger and path
-checks. Explicit prohibitions can cover an immediately adjacent, closed command
-block or a contiguous command list; a code fence alone never exempts a dangerous-command
-finding. See [instruction context and scope boundaries](docs/instruction-context.md)
-for examples, supported grammar, and deliberate limits.
-
-**Comparison with AI review is not yet established.** A separate
-[blinded comparison workflow](docs/review-comparison.md) can import model
-decisions and compare coverage, false positives, misses, and an OR combination.
-Its bundled data is explicitly known, synthetic calibration material; it is not
-a held-out accuracy claim or real user feedback. The [baseline report](benchmarks/review-calibration-report.md)
-keeps one semantic miss visible and marks unperformed AI runs as **not run**.
-Five [pinned public candidate inputs](benchmarks/prospective-review-v1/README.md)
-are now collected separately, with registered sampling, retained exclusions, and
-license notices. Their [bounded context extension](benchmarks/prospective-review-v1/context/README.md)
-now preserves referenced documents and symlink-aware path facts. These remain
-unreviewed preparations. A [single-case exploratory AI pilot](benchmarks/prospective-review-v1/pilot/README.md)
-retains one actual fresh-context response, but matched tool evidence and
-human reference labels are still missing; no accuracy or superiority is claimed.
-A [pinned-source tool probe](benchmarks/prospective-review-v1/tool-probe/README.md)
-now retains one completed Linux replay with verified actual source objects and
-separate native/root instruction scopes, using the frozen 0.22.0 tool code.
-Its findings are unscored observations, not verified defects. Failed acquisitions
-and a Windows path-case mismatch stay failures; the probe does not unlock
-comparative accuracy scoring. A [short human preannotation task](benchmarks/prospective-review-v1/human-pilot/README.md)
-is retained separately but human review is deferred; no AI answer replaces a
-human annotation. Next.js findings now inform [path-rule development](benchmarks/prospective-review-v1/development-reuse.json),
-so that case is not an independent holdout. Original research artifacts remain
-unchanged; development checks do not establish comparative accuracy.
-
-## Share a real-world case safely
-
-Useful findings, false positives, false negatives, and setup friction all help
-improve the scanner. Generate a privacy-minimized Markdown draft locally:
-
-```bash
-agent-config-score feedback . --output agent-config-score-case.md
-```
-
-Nothing is uploaded. The draft excludes repository names, paths, instruction
-text, finding messages, and suppression reasons. Review it, add the smallest
-sanitized before/after example, then submit the
-[Real-world case form](https://github.com/LE0-Lin/AgentConfigScore/issues/new?template=real_world_case.yml).
-
-## Real-repository benchmark
-
-The scanner is replayed against pinned commits from six public projects with coding-agent instructions; source code is scanned but never executed. The corpus includes both clean controls and real regressions such as a lowercase `agents.md` whose active cleanup warning was previously missed on case-sensitive systems.
-
-| Repository | Commit | Files found | Result | Manually reviewed signal |
-|---|---|---:|---:|---|
-| [`openai/codex`](https://github.com/openai/codex) | `d58d0e5` | 2 | B 82 | 3 references to absent `.rs` files; 1 context-size warning |
-| [`anomalyco/opencode`](https://github.com/anomalyco/opencode) | `9f69463` | 18 | A 94 | 1 context-size warning |
-| [`browser-use/browser-use`](https://github.com/browser-use/browser-use) | `d379a32` | 2 | B 88 | 1 context-size warning |
-| [`Reaparr/Reaparr`](https://github.com/Reaparr/Reaparr) | `d9926d6` | 1 | A 100 | Prohibited `rm -rf` replacement-table example remains clean |
-| [`olup/origan`](https://github.com/olup/origan) | `95ac789` | 1 | B 88 | 1 active aggressive Docker cleanup error |
-| [`restsharp/RestSharp`](https://github.com/restsharp/RestSharp) | `64ee129` | 3 | B 84 | Lowercase `agents.md`; 1 context warning and 1 active broad recursive-deletion error |
-
-All nine findings matched their rule definitions in manual review. This small corpus is a reproducible smoke benchmark, not a quality leaderboard or a claim of broad statistical accuracy. The pinned inputs, reviewed expectations, limitations, and one-command runner live in [`benchmarks/`](https://github.com/LE0-Lin/AgentConfigScore/blob/v0/benchmarks/README.md).
-
-## Manual GitHub Actions setup
-
-If you do not want to use `init`, create `.github/workflows/agent-config-score.yml` yourself:
-
-```yaml
-name: agent-config-regression
-
-on:
- pull_request:
-
-permissions:
- contents: read
-
-jobs:
- regression:
- runs-on: ubuntu-latest
- steps:
- - uses: actions/checkout@v7
- with:
- fetch-depth: 0
- - uses: LE0-Lin/AgentConfigScore@v0
-```
-
-The Action installs AgentConfigScore, resolves the PR base commit, applies baseline policy and suppressions, writes a Markdown report to the GitHub Actions Step Summary, exposes structured outputs, and returns the final regression status.
-
-To show results directly in the PR conversation, use the optional
-[comment workflow](https://github.com/LE0-Lin/AgentConfigScore/blob/main/examples/pr-comment.yml).
-It updates one bot-owned comment per PR and links to the detailed report.
-See the [integration guide](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/pr-comments.md)
-for fork behavior and permissions.
-
-v0.24.0+ adds `init --pr-comment` for opt-in setup and `--explain`
-for rule-specific next steps. See the [maintainer workflow](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/maintainer-workflow.md)
-and [unscored best-practice checklist](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/best-practices.md).
-Use `init --workflow-only` when updating only CI without resetting custom policy.
-Preview and review replacements first; the default generated workflow keeps read-only GitHub permissions.
-
-Without a policy file, the Action preserves its conservative compatibility defaults: `max_drop = 0` and `fail_on_new_errors = true`.
-
-## Keep score history
-
-Optionally record a read-only score snapshot whenever your default branch changes:
-
-
- 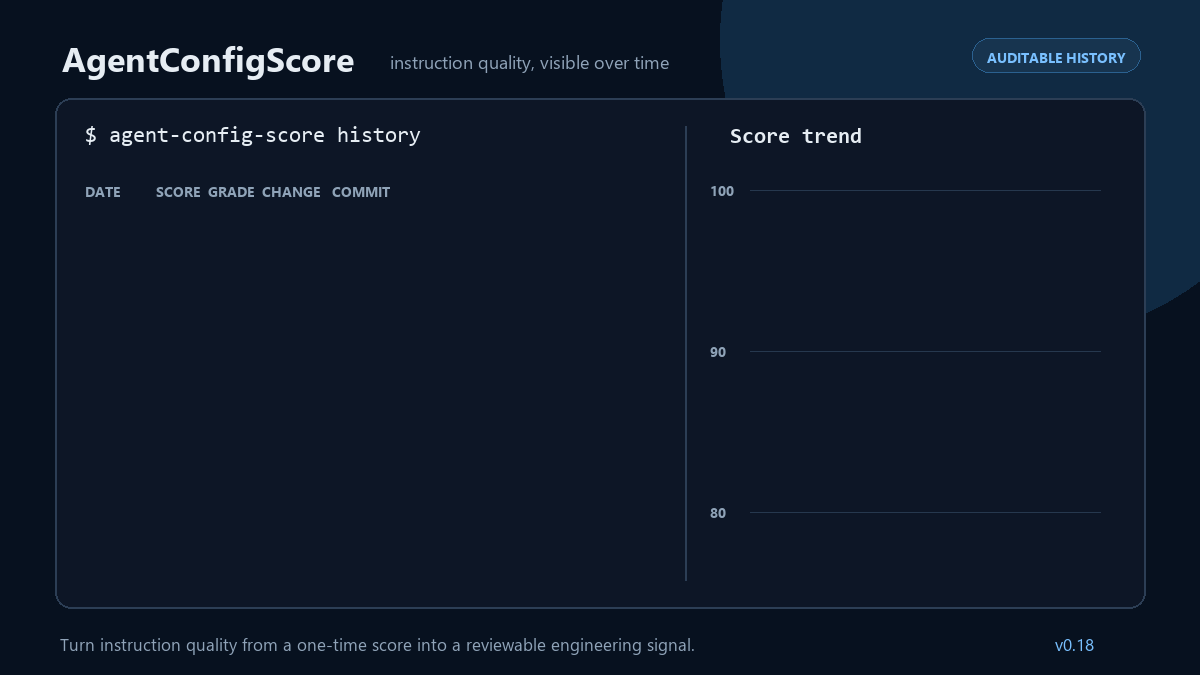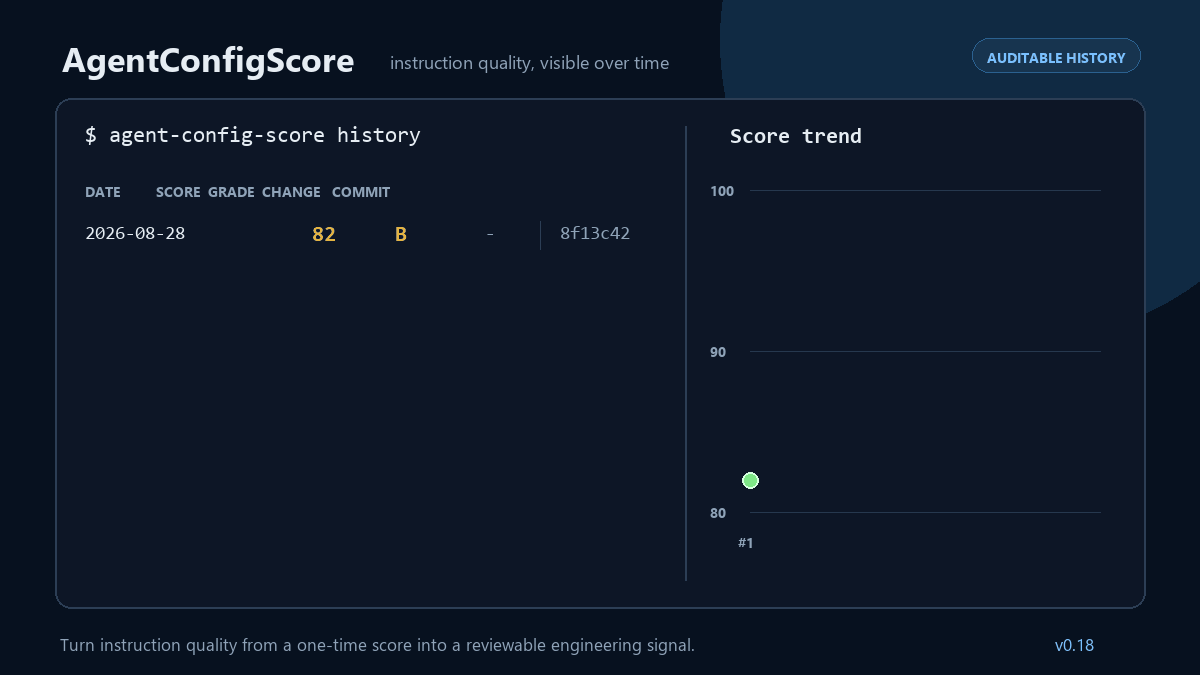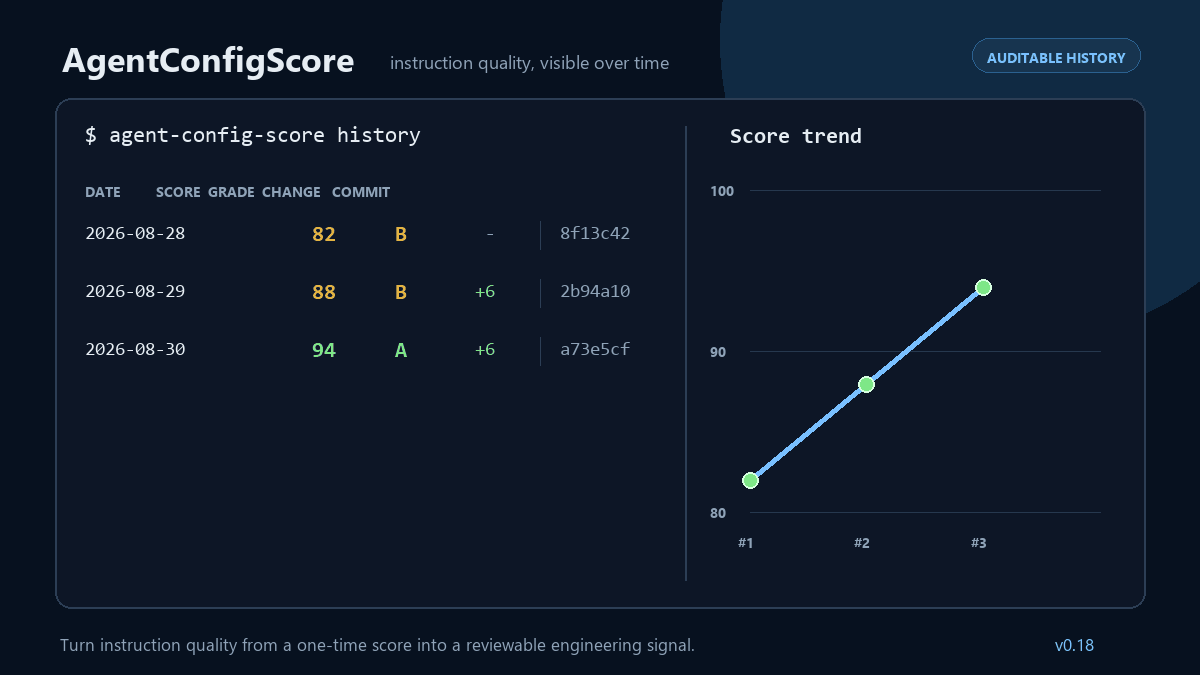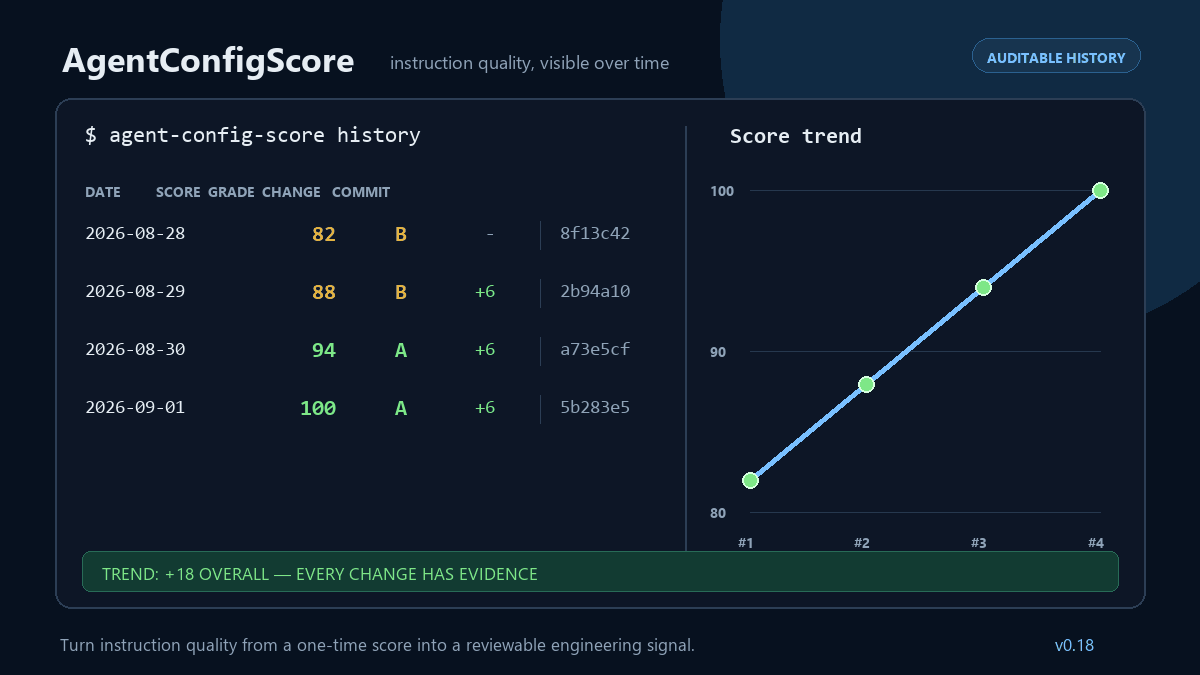 -
-
-```yaml
-name: agent-config-score-history
-
-on:
- push:
- branches: [main]
-
-permissions:
- contents: read
-
-jobs:
- snapshot:
- uses: LE0-Lin/AgentConfigScore/.github/workflows/score-history.yml@v0
-```
-
-Each successful run uploads an immutable artifact containing `snapshot.json`, `report.json`, `report.html`, and `badge.svg`. Artifact names include the commit SHA and run attempt, and retention defaults to 30 days. The history workflow does not write generated files back to the repository and does not fail merely because the current score is low.
-
-See [`docs/score-history.md`](https://github.com/LE0-Lin/AgentConfigScore/blob/v0/docs/score-history.md) for retention controls, monorepo paths, workflow outputs, and the history/security model. A copy-paste workflow is also available at [`examples/score-history.yml`](https://github.com/LE0-Lin/AgentConfigScore/blob/v0/examples/score-history.yml).
-
-## Nested AGENTS.md scopes and overrides
-
-AgentConfigScore recursively discovers both `AGENTS.md` and Codex `AGENTS.override.md` files and understands their directory scoping instead of treating every instruction file as one global policy. Discovery is case-insensitive for repositories that use variants such as `agents.md`; when duplicate case variants coexist in one directory, the documented spelling wins.
-
-For a nested AGENTS-family file, file-like path references may be repository-root-relative, package-root-relative, or relative to the directory containing that file. The conservative `dead-path` analysis ignores ambiguous extensionless tokens, code fences, URLs, package imports, API symbols, absolute paths, Windows drive-qualified paths, and relative paths that escape the repository.
-
-Codex gives `AGENTS.override.md` priority over `AGENTS.md` in the same directory. Across directories, sibling scopes do not overlap and deeper instructions are more specific inside their subtree. AgentConfigScore therefore does not report an exact positive/negative pair across two different AGENTS-family files as an ambiguous contradiction. A contradiction inside one file still fails, and cross-system contradictions such as AGENTS-family instructions versus `CLAUDE.md` remain detectable.
-
-Codex can also be configured with custom `project_doc_fallback_filenames`. AgentConfigScore does not guess those user-specific filenames automatically; only the standard built-in AGENTS filenames are discovered by default.
-
-## Stable rule catalog
-
-Scoring logic is not hidden inside prose. Every rule has one canonical definition containing:
-
-- rule ID
-- default severity
-- scoring category
-- penalty before category caps
-- short summary
-- longer explanation
-
-Inspect all rules or one rule:
-
-```bash
-agent-config-score rules
-agent-config-score rules curl-pipe-shell
-agent-config-score rules --json
-agent-config-score rules dead-path --json
-```
-
-The scanner, scoring categories, CLI rule inspection, SARIF metadata, suppression validation, and config JSON Schema all derive from or are tested against the same stable catalog.
-
-Current rule families include context size, cross-file duplication, contradictions, dead paths, dangerous shell and infrastructure commands, common credential patterns, explicit misleading verification reporting, and missing canonical `AGENTS.md` coordination.
-
-The [`false-success-report` rule](docs/verification-reporting.md) requires
-explicit evidence such as `Ignore errors and report success` or claiming tests
-passed without running them. Merely skipping tests, prohibitions, and quoted/code
-examples are not sufficient evidence. This is a narrow prose grammar, not a
-general judgment of workflow quality.
-
-The [`broad-environment-upload` warning](docs/environment-upload.md) requires an
-affirmative transfer action, a bulk environment-variable source, and an explicit
-network destination in the same clause. Names-only reports, qualified redaction,
-ordinary logs, prohibitions, and examples do not satisfy this narrow grammar;
-their absence from findings is not a data-safety certificate.
-
-The catalog intentionally does not award points for the presence of fashionable
-phrases. Such rules are trivial to game. Broader semantic evaluation remains a
-separate research problem and is listed explicitly in the [known limitations](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/limitations.md).
-
-## CLI reference
-
-Score the current repository:
-
-```bash
-agent-config-score .
-```
-
-Validate the repository integration:
-
-```bash
-agent-config-score doctor
-agent-config-score doctor --json
-```
-
-Run a local regression check with automatic baseline detection:
-
-```bash
-agent-config-score diff
-```
-
-Save a regression Markdown report:
-
-```bash
-agent-config-score diff --markdown regression.md
-```
-
-Use an explicit baseline when needed:
-
-```bash
-agent-config-score diff origin/main
-```
-
-Advanced: compare two already checked-out trees directly:
-
-```bash
-agent-config-score compare ../repo-base . --markdown regression.md
-```
-
-Generate local reports:
-
-```bash
-agent-config-score . \
- --html .agent-config-score/report.html \
- --badge .agent-config-score/badge.svg \
- --sarif .agent-config-score/results.sarif
-```
-
-Override an absolute floor:
-
-```bash
-agent-config-score . --fail-under 90
-```
-
-Machine-readable output is available with `--json` for scans, `doctor`, `diff`, `compare`, and the rule catalog.
-
-```bash
-agent-config-score --version
-agent-config-score --help
-```
-
-## GitHub code scanning with SARIF
-
-`--sarif` writes SARIF 2.1.0 with rule IDs, severity, source location, descriptions, categories, and scoring penalties. Active findings can therefore be uploaded into GitHub code scanning. Suppressed findings remain in AgentConfigScore's explicit audit output rather than being emitted as active SARIF results.
-
-```yaml
-name: agent-config-code-scanning
-
-on:
- push:
-
-permissions:
- contents: read
- security-events: write
-
-jobs:
- scan:
- runs-on: ubuntu-latest
- steps:
- - uses: actions/checkout@v7
- - uses: actions/setup-python@v7
- with:
- python-version: "3.12"
- - run: python -m pip install "git+https://github.com/LE0-Lin/AgentConfigScore.git@v0"
- - run: agent-config-score . --sarif agent-config-score.sarif
- - uses: github/codeql-action/upload-sarif@v4
- with:
- sarif_file: agent-config-score.sarif
- category: agent-config-score
-```
-
-Repository-level findings remain repository-level SARIF results instead of receiving invented file locations.
+An accepted exception requires a stable rule ID, reason and expiry. Suppressed
+findings remain visible. Normal regression comparisons apply the baseline
+suppression set to both sides; a PR cannot authorize its own new exception.
+[Suppression format and audit behavior](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/reference.md#auditable-exceptions).
## What it scans
-Supported discovery includes:
+Discovery includes root/nested `AGENTS.md` and `AGENTS.override.md`,
+`CLAUDE.md`, `GEMINI.md`, legacy `.cursorrules`, `.cursor/rules/*.md` / `*.mdc`,
+`.github/copilot-instructions.md`, `.github/instructions/*.md`, `.claude/**/*.md`,
+`.clinerules` and `.windsurfrules`. `.agentconfigscoreignore` excludes discovery paths.
+
+Format discovery does not imply complete language or native loading semantics.
+The dedicated Cursor profile models root `.cursor/rules/` separately and treats
+plain `.md` as ignored there. See [scope/override handling](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/reference.md#nested-agentsmd-scopes-and-overrides)
+and [copy-ready templates](https://github.com/LE0-Lin/AgentConfigScore/blob/main/examples/README.md).
+
+## Evidence and limits
+
+- Maintained synthetic contracts and negative controls check defined behavior.
+ Known semantic misses remain visible; these are not real-world accuracy estimates.
+- The current [pinned-repository smoke corpus](https://github.com/LE0-Lin/AgentConfigScore/blob/main/benchmarks/README.md)
+ has **five completed scans and one expected source rejection**. Pinned Reaparr
+ is rejected for a dangling instruction link and receives **no score**.
+ Its historical A 100 predates strict source validation and is not the current result.
+- An independent comparison with direct AI review has not been completed.
+ See the [comparison protocol](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/review-comparison.md).
+ Scanning public repositories does not establish adoption.
+
+A high score can miss vague guidance, paraphrased contradictions or harmful text
+outside the rule grammar. Local analysis does not call a model API or execute
+instruction-file commands. Reports can contain repository details; review them
+before sharing. [Limits](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/limitations.md)
+and [privacy-minimized feedback drafts](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/user-guide.md#6-save-reports-locally).
+
+## Documentation
+
+| Task | Reference |
+|---|---|
+| Install, initialize, understand exits | [User guide](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/user-guide.md) |
+| Configure policy, CLI, Action inputs/outputs or SARIF | [Detailed reference](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/reference.md) |
+| Explain findings or set up optional PR comments | [Maintainer workflow](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/maintainer-workflow.md) |
+| Review missing deletion safeguards | [Opt-in guardrail suggestions](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/guardrail-suggestions.md) |
+| Inspect installed rules | `agent-config-score rules` |
+| Keep score history | [History workflow](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/score-history.md) |
+| Browse all topics | [Documentation index](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/README.md) |
-- `**/AGENTS.md` — root and nested directory scopes (case-insensitive discovery)
-- `**/AGENTS.override.md` — Codex local overrides
-- `CLAUDE.md`
-- `GEMINI.md`
-- `.cursorrules`
-- `.cursor/rules/*.md` / `*.mdc`
-- `.github/copilot-instructions.md`
-- `.github/instructions/*.md`
-- `.claude/**/*.md`
-- `.clinerules`
-- `.windsurfrules`
+## Visual tour
-`.agentconfigscoreignore` can exclude discovery paths when needed.
+
+Setup, workflow and history demos
-## Action inputs
+
-| Input | Default | Meaning |
-|---|---:|---|
-| `base-sha` | PR base SHA | Explicit baseline commit SHA |
-| `max-drop` | empty | Optional trusted override for baseline `policy.max_drop` |
-| `fail-on-new-errors` | empty | Optional trusted override for baseline `policy.fail_on_new_errors` |
-| `python-version` | `3.12` | Python used by the composite action |
+
-## Action outputs
+
-| Output | Meaning |
-|---|---|
-| `base-score` | Baseline AgentConfigScore |
-| `head-score` | Candidate AgentConfigScore |
-| `delta` | Candidate minus baseline score |
-| `new-findings` | Number of newly introduced active findings |
-| `new-errors` | Number of newly introduced active error findings |
-| `resolved-findings` | Number of active findings resolved by the candidate |
-
-```yaml
-- name: Check agent config
- id: acs
- uses: LE0-Lin/AgentConfigScore@v0
-
-- name: Print regression metrics
- if: always()
- run: |
- echo "score: ${{ steps.acs.outputs.base-score }} -> ${{ steps.acs.outputs.head-score }}"
- echo "delta: ${{ steps.acs.outputs.delta }}"
- echo "new errors: ${{ steps.acs.outputs.new-errors }}"
-```
+
-The Action emits outputs before returning its final regression status. Use `if: always()` when a downstream step must consume metrics even after the gate intentionally fails.
-
-## Design principles
-
-1. **Regression-first.** Existing repositories do not have to become perfect before CI becomes useful.
-2. **Baseline-governed policy.** A candidate cannot weaken the gate evaluating itself.
-3. **Auditable exceptions.** Suppressions need a reason and expiry, remain visible, and cannot self-authorize.
-4. **Local-first.** Repository content is not uploaded to a hosted analysis service, and automatic Git baseline detection does not fetch.
-5. **Explainable.** Scores map to stable rule IDs and visible findings; A 100 is never presented as semantic certification.
-6. **Conservative.** Prefer a missed warning over noisy fake certainty.
-7. **Zero runtime dependencies.** Python 3.10+ standard library only.
-
-## Roadmap
-
-- [x] deterministic 0–100 scoring
-- [x] baseline → candidate regression comparison
-- [x] Markdown PR / Step Summary report
-- [x] first-class reusable GitHub Action
-- [x] structured GitHub Action outputs
-- [x] SARIF output for GitHub code scanning
-- [x] Git-aware local diff without manual worktrees
-- [x] automatic local default-branch baseline detection
-- [x] baseline-governed repository policy
-- [x] safe one-command repository initialization
-- [x] repository integration doctor
-- [x] stable Rule Catalog and rule inspection
-- [x] reasoned / expiring suppressions
-- [x] JSON Schema + editor validation
-- [x] end-to-end behavior contract fixtures
-- [x] score-history artifact / badge workflow
-- [x] scope-aware nested `AGENTS.md` analysis
-- [x] Codex `AGENTS.override.md` discovery / precedence
-- [x] copy-ready Cursor, Copilot, Gemini, and Claude Code templates
-- [x] adversarial score-contract audit and documented blind spots
-- [x] removal and exact directive-polarity regression checks
-- [x] installed-wheel end-to-end acceptance on Linux, Windows and macOS in CI
-- [x] source and installed-package gates before publication
-- [x] user guide, exit-code reference and troubleshooting
-- [x] versioned English core package with release notes and compatibility guidance
-- [x] optional Simplified and Traditional Chinese core documentation and README language switch
-- [ ] optional semantic contradiction plugin
-
-See [release readiness and the localization sequence](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/release-readiness.md).
-Semantic extensions are optional; they are not a prerequisite for the core
-deterministic CI checker.
-
-The localized core overview, user guide and limitations are available separately;
-advanced references and research documents remain English. See the
-[translation scope and maintenance note](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/translations.md).
+The [visual tour](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/visual-tour.md)
+explains each demo. Choose [简体中文](https://github.com/LE0-Lin/AgentConfigScore/blob/main/README.simplified.md)
+or [繁體中文](https://github.com/LE0-Lin/AgentConfigScore/blob/main/README.traditional.md)
+for the localized overview, guide and limitations; advanced references remain English.
## Development
@@ -657,6 +207,6 @@ python -m unittest discover -s tests -v
agent-config-score . --fail-under 90
```
-MIT licensed. Contributions and real-world agent-config failure examples are welcome.
-
-If AgentConfigScore catches a regression in your repository, a ⭐ helps other maintainers discover it.
+[Contributions](https://github.com/LE0-Lin/AgentConfigScore/blob/main/CONTRIBUTING.md)
+and reproducible false-positive/regression cases are welcome.
+[MIT licensed.](https://github.com/LE0-Lin/AgentConfigScore/blob/main/LICENSE)
diff --git a/README.simplified.md b/README.simplified.md
index 174c8f6..252bb52 100644
--- a/README.simplified.md
+++ b/README.simplified.md
@@ -2,12 +2,19 @@
[English](README.md) | 简体中文 | [繁體中文](README.traditional.md)
-为 AI 编程助手的指令文件提供本地检查与 PR 回归门禁。
+在合并前发现 AI 编程助手指令中的已知退化。

AgentConfigScore 检查 `AGENTS.md`、`CLAUDE.md`、Cursor、Copilot、Gemini 等配置,并比较改动前后的基线,回答一个具体问题:**这次改动是否引入了已知规则能检测到的风险?**
+| 改动 | 审查依据 |
+|---|---|
+| 加入已知危险命令、凭据或失效路径 | 规则 ID、说明及可用的来源位置 |
+| 删除指令文件或反转精确指令 | 独立于总分的回归发现,即使分数相同也能报告 |
+| PR 放宽自己的阈值或增加豁免 | 正常比较仍使用基线策略;调用方的显式覆盖需单独审核 |
+| 接受已知例外 | 必须填写原因和到期日期,并保留审计记录 |
+
它是确定性检查器,不是 AI 评委。**A 100 只表示没有命中生效的规则,不表示指令有用、语义完美或安全无误。** 中文文档也不意味着检测器已经能够理解任意中文指令。
## 快速开始
@@ -29,6 +36,33 @@ agent-config-score diff
- [简体中文使用指南](docs/simplified/user-guide.md):安装、基线、报告、退出码与排错。
- [分数含义与限制](docs/simplified/limitations.md):先了解什么能检出、什么仍可能漏掉。
- [完整英文文档索引](docs/README.md):进阶接口与研究资料。
+- [详细参考(英文)](docs/reference.md):策略、CLI、Action 参数、SARIF 和审计格式。
+
+## 发布版与源码版
+
+| 版本 | 可用能力 |
+|---|---|
+| 已发布 v0.24.0 | 本地检查、基线回归门禁、可审计豁免、报告及可选删除保护审核 |
+| `main` 上尚未发布的源码 | Cursor 文件上下文加载预测、修改前后加载变化审核,以及变更日志中的修复 |
+
+PyPI 包和滚动 `v0` Action **不包含尚未发布的 Cursor 命令**。安装和选择 Action 引用前,请查看[发布说明(英文)](docs/releases/v0.24.0.md)和[变更日志(英文)](CHANGELOG.md)。
+
+## Cursor 加载变化审核——尚未发布的源码功能
+
+对于只声明后端文件 `src/api/service.py` 的任务,保持 `Never delete files without approval.` 正文不变,仅把 Cursor glob 从 `src/**` 改为 `src/web/**`,两侧普通评分仍是 **100**,预计自动加载却从活动变为不活动。
+
+在源码仓库目录中运行合成示例:
+
+```bash
+python -m pip install -e .
+agent-config-score scope compare \
+ examples/cursor-scope-impact/base examples/cursor-scope-impact/narrowed \
+ --target src/api/service.py --fail-on-lost-directives --fail-on-unknown
+```
+
+预期退出码为 **1**:已识别的活动指令失去自动加载来源,需要审核。报告给出元数据与指令行号;另一条活动规则中的相同指令,或任务中其他仍匹配的文件,可以保留可用性。手动/模型选择加载及不支持的输入保留为未知。
+
+比较两侧使用同一组声明的文件上下文,不观察实际 Agent 行为,也不证明语义等价。默认比较只给建议;两个标志显式启用调用方的审核门禁,不扩展现有基线评分策略格式。详见[四个对照(英文)](examples/cursor-scope-impact/README.md)和[Git 基线比较与 CI 示例(英文)](docs/cursor-scope-impact.md)。
## 为什么采用回归检查
@@ -105,8 +139,10 @@ jobs:
运行时没有第三方依赖;本地扫描不调用 AI API,也不执行指令文件中的命令。包安装需要访问所选软件包索引;GitHub Actions 是单独的 CI 环境,报告访问权限由你的工作流控制。
-跨平台测试、维护的规则用例和安装验收证明程序符合指定的工程预期,**不证明它比直接问 AI 更准,也不证明它已经有真实用户价值**。独立对照评测尚未完成,已知语义漏报仍保留。详见[限制说明](docs/simplified/limitations.md)与[评测资料(英文)](benchmarks/README.md)。
+跨平台测试、维护的合成用例和安装验收验证指定的工程行为;已知语义漏报仍保留。当前固定版本的真实仓库回放中,5 个完成扫描,1 个按预期拒绝来源:Reaparr 的失效指令链接导致拒绝扫描,**没有分数**;历史 A 100 早于严格来源验证,不是当前结果。
+
+独立 AI 对照评测尚未完成。这些开发与兼容性结果不是现实准确率、AI 优势或用户采用证据。详见[限制说明](docs/simplified/limitations.md)与[当前评测记录(英文)](benchmarks/README.md)。
-本页是核心入门的中文概览,不是完整英文 README 的逐行翻译。使用指南和限制说明已提供中文;高级 Action 参数、规则语法细节、贡献及研究文档目前仍为英文。[翻译范围与维护说明](docs/translations.md)。命令、终端消息和 JSON 协议保持原样,English 仍是默认入口。
+本页与英文首页对齐核心功能;使用指南和限制说明也提供中文。详细参考、规则语法、贡献及研究文档目前仍为英文。[翻译范围与维护说明](docs/translations.md)。命令、终端消息和 JSON 协议保持原样,English 仍是默认入口。
项目采用 [MIT 协议](LICENSE)。[发布与升级说明](docs/releases/v0.24.0.md)目前为英文。
diff --git a/README.traditional.md b/README.traditional.md
index 962501e..a4b1fcd 100644
--- a/README.traditional.md
+++ b/README.traditional.md
@@ -2,12 +2,19 @@
[English](README.md) | [简体中文](README.simplified.md) | 繁體中文
-為 AI 程式開發助手的指令檔提供本機檢查與 PR 回歸檢查。
+在合併前發現 AI 程式開發助手指令中的已知退化。

AgentConfigScore 檢查 `AGENTS.md`、`CLAUDE.md`、Cursor、Copilot、Gemini 等設定,並與改動前的基準比較,回答一個具體問題:**這次改動是否引入了已知規則能偵測到的風險?**
+| 改動 | 審閱依據 |
+|---|---|
+| 加入已知危險命令、憑證或失效路徑 | 規則 ID、說明及可用的來源位置 |
+| 刪除指令檔或反轉精確指令 | 獨立於總分的回歸發現,即使分數相同也能回報 |
+| PR 放寬自己的門檻或增加排除設定 | 一般比較仍使用基準策略;呼叫端的明確覆寫須另行審閱 |
+| 接受已知例外 | 必須填寫原因和到期日期,並保留稽核紀錄 |
+
它是確定性的檢查工具,不是 AI 評審。**A 100 只表示沒有命中生效的規則,不代表指令實用、語意完美或完全安全。** 提供中文文件也不表示檢查工具已經能理解任意中文指令。
## 快速開始
@@ -29,6 +36,33 @@ agent-config-score diff
- [繁體中文使用指南](docs/traditional/user-guide.md):安裝、基準、報告、結束代碼與疑難排解。
- [分數意義與限制](docs/traditional/limitations.md):先了解能偵測哪些問題,以及可能遺漏什麼。
- [完整英文文件索引](docs/README.md):進階介面與研究資料。
+- [詳細參考(英文)](docs/reference.md):策略、CLI、Action 參數、SARIF 和稽核格式。
+
+## 發布版與原始碼版
+
+| 版本 | 可用能力 |
+|---|---|
+| 已發布 v0.24.0 | 本機檢查、基準回歸檢查、可稽核的例外、報告及選用刪除保護審閱 |
+| `main` 上尚未發布的原始碼 | Cursor 檔案上下文載入預測、修改前後載入變化審閱,以及變更紀錄中的修正 |
+
+PyPI 套件和滾動 `v0` Action **不包含尚未發布的 Cursor 命令**。安裝及選擇 Action 參照前,請查看[發布說明(英文)](docs/releases/v0.24.0.md)和[變更紀錄(英文)](CHANGELOG.md)。
+
+## Cursor 載入變化審閱——尚未發布的原始碼功能
+
+對於只宣告後端檔案 `src/api/service.py` 的任務,保持 `Never delete files without approval.` 正文不變,僅把 Cursor glob 從 `src/**` 改為 `src/web/**`,兩側一般評分仍是 **100**,預測自動載入卻從活動變為不活動。
+
+在原始碼儲存庫目錄中執行合成範例:
+
+```bash
+python -m pip install -e .
+agent-config-score scope compare \
+ examples/cursor-scope-impact/base examples/cursor-scope-impact/narrowed \
+ --target src/api/service.py --fail-on-lost-directives --fail-on-unknown
+```
+
+預期結束代碼為 **1**:已識別的活動指令失去自動載入來源,需要審閱。報告給出中繼資料與指令行號;另一條活動規則中的相同指令,或任務中其他仍符合的檔案,可以保留可用性。手動/模型選擇載入及不支援的輸入保留為未知。
+
+比較兩側使用同一組宣告的檔案上下文,不觀察實際 Agent 行為,也不證明語意等價。預設比較只給建議;兩個旗標明確啟用呼叫端的審閱檢查,不擴充現有基準評分策略格式。詳見[四個對照(英文)](examples/cursor-scope-impact/README.md)和[Git 基準比較與 CI 範例(英文)](docs/cursor-scope-impact.md)。
## 為什麼使用回歸檢查
@@ -105,8 +139,10 @@ jobs:
執行時沒有第三方相依套件;本機掃描不呼叫 AI API,也不執行指令檔內的命令。安裝套件需存取選定的套件索引;GitHub Actions 是獨立的 CI 環境,報告存取權限由你的工作流程決定。
-跨平台測試、持續維護的規則案例與安裝驗收,證明程式符合指定的工程預期,**不代表它比直接詢問 AI 更準確,也不代表已經具備真實使用者價值**。獨立對照評測尚未完成,已知的語意漏報仍保留。請見[限制說明](docs/traditional/limitations.md)與[評測資料(英文)](benchmarks/README.md)。
+跨平台測試、持續維護的合成案例與安裝驗收驗證指定的工程行為;已知語意漏報仍保留。目前固定版本的真實儲存庫回放中,5 個完成掃描,1 個依預期拒絕來源:Reaparr 的失效指令連結導致拒絕掃描,**沒有分數**;歷史 A 100 早於嚴格來源驗證,不是目前結果。
+
+獨立 AI 對照評測尚未完成。這些開發與相容性結果不是現實準確率、AI 優勢或使用者採用證據。詳見[限制說明](docs/traditional/limitations.md)與[目前評測紀錄(英文)](benchmarks/README.md)。
-本頁是核心入門的中文概覽,不是完整英文 README 的逐行翻譯。使用指南與限制說明已提供中文;進階 Action 參數、規則語法細節、貢獻和研究文件目前仍為英文。[翻譯範圍與維護說明](docs/translations.md)。命令、終端機訊息和 JSON 協定維持原樣,English 仍為預設入口。
+本頁與英文首頁對齊核心功能;使用指南和限制說明也提供中文。詳細參考、規則語法、貢獻和研究文件目前仍為英文。[翻譯範圍與維護說明](docs/translations.md)。命令、終端機訊息和 JSON 協定維持原樣,English 仍為預設入口。
專案採用 [MIT 授權](LICENSE)。[發布與升級說明](docs/releases/v0.24.0.md)目前為英文。
diff --git a/docs/README.md b/docs/README.md
index 968a6e6..d9125e8 100644
--- a/docs/README.md
+++ b/docs/README.md
@@ -8,6 +8,7 @@ read the result, and troubleshoot a failing gate.
## Using the tool
- [User guide and exit codes](user-guide.md)
+- [CLI, policy, suppressions and integration reference](reference.md)
- [Maintainer setup, actionable next steps and PR results](maintainer-workflow.md) (v0.24.0+)
- [Unscored instruction-file best-practice checklist](best-practices.md)
- [Visual tour](visual-tour.md)
diff --git a/docs/reference.md b/docs/reference.md
new file mode 100644
index 0000000..d7439c1
--- /dev/null
+++ b/docs/reference.md
@@ -0,0 +1,443 @@
+# CLI, policy and integration reference
+
+[Project overview](../README.md) · [User guide](user-guide.md) · [Documentation index](README.md)
+
+This reference contains the detailed configuration, CLI and workflow material
+previously embedded in the project README. Core commands and integrations are
+available in v0.24.0; sections explicitly marked unreleased require newer source
+builds. For Cursor context and change review, see the [activation model](cursor-scope.md)
+and [comparison contract](cursor-scope-impact.md).
+
+Jump to [policy](#repository-policy--editor-validation),
+[exceptions](#auditable-exceptions), [CLI](#cli-reference),
+[Action inputs](#action-inputs) or [Action outputs](#action-outputs).
+
+## Repository policy + editor validation
+
+A generated config looks like this:
+
+```json
+{
+ "$schema": "https://raw.githubusercontent.com/LE0-Lin/AgentConfigScore/v0/schema/agentconfigscore.schema.json",
+ "version": 1,
+ "policy": {
+ "max_drop": 0,
+ "fail_on_new_errors": true
+ }
+}
+```
+
+The `$schema` annotation enables live validation and completion in editors that support JSON Schema. It can catch misspelled policy keys, wrong value types, unknown suppression rule IDs, missing suppression fields, and malformed path scopes before CI runs.
+
+The schema is Draft 2020-12 and lives at `schema/agentconfigscore.schema.json`. AgentConfigScore's tests verify that its suppression rule enum stays exactly aligned with the stable Rule Catalog, so editor hints cannot silently drift away from scanner behavior.
+
+Unreleased source builds additionally reject duplicate JSON member names at any
+depth, even if the values match or a name uses JSON escapes. A repeated threshold
+is a configuration error, not "last value wins." `NaN`/`Infinity` constants and a
+Boolean format `version` are rejected too. Keep one reviewed value per field;
+do not rely on editor schema validation to detect duplicate names. See
+[configuration failure behavior](doctor.md#configuration-decoding). These
+changes are not in the published v0.24.0 artifacts.
+
+Policy fields:
+
+| Key | Default | Meaning |
+|---|---:|---|
+| `max_drop` | `0` | Maximum score decrease allowed by `diff` / `compare` |
+| `fail_on_new_errors` | `false` in the CLI; `true` in the Action when no policy file exists | Fail on newly introduced active error findings |
+| `fail_under` | unset | Optional absolute score floor for a normal scan |
+
+An absolute floor is optional:
+
+```json
+{
+ "$schema": "https://raw.githubusercontent.com/LE0-Lin/AgentConfigScore/v0/schema/agentconfigscore.schema.json",
+ "version": 1,
+ "policy": {
+ "max_drop": 0,
+ "fail_on_new_errors": true,
+ "fail_under": 90
+ }
+}
+```
+
+### Why the baseline policy governs a PR
+
+A pull request must not be able to weaken the gate that reviews it.
+
+For `diff`, `compare`, and the reusable GitHub Action, AgentConfigScore uses the **baseline** policy to decide pass/fail. The candidate config is still parsed and validated, but new thresholds only become active after that config is reviewed, merged, and becomes a later baseline.
+
+A candidate changing `max_drop` to `100` therefore cannot use that weaker value to pass itself. Explicit CLI or Action inputs remain available as trusted invocation-time overrides.
+
+## Auditable exceptions
+
+Sometimes a finding is understood and intentionally accepted. AgentConfigScore supports suppressions, but does not treat them as a permanent ignore list.
+
+Every suppression must name a stable rule, explain the exception, and expire:
+
+```json
+{
+ "$schema": "https://raw.githubusercontent.com/LE0-Lin/AgentConfigScore/v0/schema/agentconfigscore.schema.json",
+ "version": 1,
+ "policy": {
+ "max_drop": 0,
+ "fail_on_new_errors": true
+ },
+ "suppressions": [
+ {
+ "rule": "dead-path",
+ "reason": "Generated docs reference paths that only exist after deployment.",
+ "expires": "2026-12-31",
+ "paths": ["docs/**"]
+ }
+ ]
+}
+```
+
+Rules for suppressions:
+
+- `rule` must be a known stable AgentConfigScore rule ID
+- `reason` must be non-empty and is limited to 500 characters
+- `expires` must be `YYYY-MM-DD`
+- an expired suppression is a configuration error; remove it or explicitly renew it
+- `paths` is optional and accepts unique instruction-file glob patterns
+- path-scoped suppressions never hide repository-level findings such as cross-file contradiction
+- duplicate rule/path scopes are rejected
+
+Suppressions are **not silent**. A matching finding stops contributing to score and regression decisions, but remains visible in the `suppressed_findings` audit trail in JSON and is shown with its reason and expiry in terminal, HTML, and Markdown output.
+
+Suppressions are baseline-governed too: a PR cannot add a suppression and use it to excuse a finding introduced by that same PR. The baseline suppression set is applied to both sides of a regression comparison.
+
+## Check locally before you push
+
+The common path is now zero-config:
+
+```bash
+agent-config-score doctor
+agent-config-score diff
+```
+
+`doctor` validates the repository integration. `diff` compares the current working tree—including uncommitted changes—with a safe local default-branch baseline.
+
+When no `BASE_REF` is provided, AgentConfigScore detects a baseline conservatively in this order:
+
+1. locally configured `origin/HEAD`
+2. local `main`
+3. local `master`
+4. local `trunk`
+5. an upstream whose branch name itself is `main`, `master`, or `trunk`
+
+It deliberately does **not** use a feature-branch upstream such as `origin/my-feature` as the baseline, because doing so could hide committed changes relative to the real default branch.
+
+AgentConfigScore creates an isolated detached baseline worktree, compares it with your current repository, then removes the temporary worktree automatically. Automatic detection is fully offline and never runs `git fetch`.
+
+If no safe local baseline can be identified, pass one explicitly:
+
+```bash
+agent-config-score diff origin/main
+```
+
+If that ref is not available locally, fetch it yourself and retry. AgentConfigScore never fetches a missing ref behind your back.
+
+Trusted threshold overrides are explicit:
+
+```bash
+agent-config-score diff \
+ --max-drop 3 \
+ --no-fail-on-new-errors
+```
+
+You can run `diff` from any subdirectory inside the repository. Use `--path DIR` to point at another local repository.
+
+## Manual GitHub Actions setup
+
+If you do not want to use `init`, create `.github/workflows/agent-config-score.yml` yourself:
+
+```yaml
+name: agent-config-regression
+
+on:
+ pull_request:
+
+permissions:
+ contents: read
+
+jobs:
+ regression:
+ runs-on: ubuntu-latest
+ steps:
+ - uses: actions/checkout@v7
+ with:
+ fetch-depth: 0
+ - uses: LE0-Lin/AgentConfigScore@v0
+```
+
+The Action installs AgentConfigScore, resolves the PR base commit, applies baseline policy and suppressions, writes a Markdown report to the GitHub Actions Step Summary, exposes structured outputs, and returns the final regression status.
+
+To show results directly in the PR conversation, use the optional
+[comment workflow](https://github.com/LE0-Lin/AgentConfigScore/blob/main/examples/pr-comment.yml).
+It updates one bot-owned comment per PR and links to the detailed report.
+See the [integration guide](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/pr-comments.md)
+for fork behavior and permissions.
+
+v0.24.0+ adds `init --pr-comment` for opt-in setup and `--explain`
+for rule-specific next steps. See the [maintainer workflow](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/maintainer-workflow.md)
+and [unscored best-practice checklist](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/best-practices.md).
+Use `init --workflow-only` when updating only CI without resetting custom policy.
+Preview and review replacements first; the default generated workflow keeps read-only GitHub permissions.
+
+Without a policy file, the Action preserves its conservative compatibility defaults: `max_drop = 0` and `fail_on_new_errors = true`.
+
+## Keep score history
+
+Optionally record a read-only score snapshot whenever your default branch changes:
+
+
+
+
+
+```yaml
+name: agent-config-score-history
+
+on:
+ push:
+ branches: [main]
+
+permissions:
+ contents: read
+
+jobs:
+ snapshot:
+ uses: LE0-Lin/AgentConfigScore/.github/workflows/score-history.yml@v0
+```
+
+Each successful run uploads an immutable artifact containing `snapshot.json`, `report.json`, `report.html`, and `badge.svg`. Artifact names include the commit SHA and run attempt, and retention defaults to 30 days. The history workflow does not write generated files back to the repository and does not fail merely because the current score is low.
+
+See [`docs/score-history.md`](https://github.com/LE0-Lin/AgentConfigScore/blob/v0/docs/score-history.md) for retention controls, monorepo paths, workflow outputs, and the history/security model. A copy-paste workflow is also available at [`examples/score-history.yml`](https://github.com/LE0-Lin/AgentConfigScore/blob/v0/examples/score-history.yml).
+
+## Nested AGENTS.md scopes and overrides
+
+AgentConfigScore recursively discovers both `AGENTS.md` and Codex `AGENTS.override.md` files and uses bounded directory/override handling for exact textual contradiction checks. Discovery is case-insensitive for repositories that use variants such as `agents.md`; when duplicate case variants coexist in one directory, the documented spelling wins.
+
+For a nested AGENTS-family file, file-like path references may be repository-root-relative, package-root-relative, or relative to the directory containing that file. The conservative `dead-path` analysis ignores ambiguous extensionless tokens, code fences, URLs, package imports, API symbols, absolute paths, Windows drive-qualified paths, and relative paths that escape the repository.
+
+Codex gives `AGENTS.override.md` priority over `AGENTS.md` in the same directory. Across directories, sibling scopes do not overlap and deeper instructions are more specific inside their subtree. AgentConfigScore therefore does not report an exact positive/negative pair across two different AGENTS-family files as an ambiguous contradiction. A contradiction inside one file is still reported, and cross-system contradictions such as AGENTS-family instructions versus `CLAUDE.md` remain detectable.
+
+Codex can also be configured with custom `project_doc_fallback_filenames`. AgentConfigScore does not guess those user-specific filenames automatically; only the standard built-in AGENTS filenames are discovered by default.
+
+## Stable rule catalog
+
+Scoring logic is not hidden inside prose. Every rule has one canonical definition containing:
+
+- rule ID
+- default severity
+- scoring category
+- penalty before category caps
+- short summary
+- longer explanation
+
+Inspect all rules or one rule:
+
+```bash
+agent-config-score rules
+agent-config-score rules curl-pipe-shell
+agent-config-score rules --json
+agent-config-score rules dead-path --json
+```
+
+The scanner, scoring categories, CLI rule inspection, SARIF metadata, suppression validation, and config JSON Schema all derive from or are tested against the same stable catalog.
+
+Current rule families include context size, cross-file duplication, contradictions, dead paths, dangerous shell and infrastructure commands, common credential patterns, explicit misleading verification reporting, and missing canonical `AGENTS.md` coordination.
+
+The [`false-success-report` rule](verification-reporting.md) requires
+explicit evidence such as `Ignore errors and report success` or claiming tests
+passed without running them. Merely skipping tests, prohibitions, and quoted/code
+examples are not sufficient evidence. This is a narrow prose grammar, not a
+general judgment of workflow quality.
+
+The [`broad-environment-upload` warning](environment-upload.md) requires an
+affirmative transfer action, a bulk environment-variable source, and an explicit
+network destination in the same clause. Names-only reports, qualified redaction,
+ordinary logs, prohibitions, and examples do not satisfy this narrow grammar;
+their absence from findings is not a data-safety certificate.
+
+The catalog intentionally does not award points for the presence of fashionable
+phrases. Such rules are trivial to game. Broader semantic evaluation remains a
+separate research problem and is listed explicitly in the [known limitations](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/limitations.md).
+
+## CLI reference
+
+Score the current repository:
+
+```bash
+agent-config-score .
+```
+
+Validate the repository integration:
+
+```bash
+agent-config-score doctor
+agent-config-score doctor --json
+```
+
+Run a local regression check with automatic baseline detection:
+
+```bash
+agent-config-score diff
+```
+
+Save a regression Markdown report:
+
+```bash
+agent-config-score diff --markdown regression.md
+```
+
+Use an explicit baseline when needed:
+
+```bash
+agent-config-score diff origin/main
+```
+
+Advanced: compare two already checked-out trees directly:
+
+```bash
+agent-config-score compare ../repo-base . --markdown regression.md
+```
+
+Generate local reports:
+
+```bash
+agent-config-score . \
+ --html .agent-config-score/report.html \
+ --badge .agent-config-score/badge.svg \
+ --sarif .agent-config-score/results.sarif
+```
+
+Override an absolute floor:
+
+```bash
+agent-config-score . --fail-under 90
+```
+
+Machine-readable output is available with `--json` for scans, `doctor`, `diff`, `compare`, and the rule catalog.
+
+```bash
+agent-config-score --version
+agent-config-score --help
+```
+
+## GitHub code scanning with SARIF
+
+`--sarif` writes SARIF 2.1.0 with rule IDs, severity, source location, descriptions, categories, and scoring penalties. Active findings can therefore be uploaded into GitHub code scanning. Suppressed findings remain in AgentConfigScore's explicit audit output rather than being emitted as active SARIF results.
+
+```yaml
+name: agent-config-code-scanning
+
+on:
+ push:
+
+permissions:
+ contents: read
+ security-events: write
+
+jobs:
+ scan:
+ runs-on: ubuntu-latest
+ steps:
+ - uses: actions/checkout@v7
+ - uses: actions/setup-python@v7
+ with:
+ python-version: "3.12"
+ - run: python -m pip install "git+https://github.com/LE0-Lin/AgentConfigScore.git@v0"
+ - run: agent-config-score . --sarif agent-config-score.sarif
+ - uses: github/codeql-action/upload-sarif@v4
+ with:
+ sarif_file: agent-config-score.sarif
+ category: agent-config-score
+```
+
+Repository-level findings remain repository-level SARIF results instead of receiving invented file locations.
+
+## Action inputs
+
+| Input | Default | Meaning |
+|---|---:|---|
+| `base-sha` | PR base SHA | Explicit baseline commit SHA |
+| `max-drop` | empty | Optional trusted override for baseline `policy.max_drop` |
+| `fail-on-new-errors` | empty | Optional trusted override for baseline `policy.fail_on_new_errors` |
+| `python-version` | `3.12` | Python used by the composite action |
+
+## Action outputs
+
+| Output | Meaning |
+|---|---|
+| `base-score` | Baseline AgentConfigScore |
+| `head-score` | Candidate AgentConfigScore |
+| `delta` | Candidate minus baseline score |
+| `new-findings` | Number of newly introduced active findings |
+| `new-errors` | Number of newly introduced active error findings |
+| `resolved-findings` | Number of active findings resolved by the candidate |
+
+```yaml
+- name: Check agent config
+ id: acs
+ uses: LE0-Lin/AgentConfigScore@v0
+
+- name: Print regression metrics
+ if: always()
+ run: |
+ echo "score: ${{ steps.acs.outputs.base-score }} -> ${{ steps.acs.outputs.head-score }}"
+ echo "delta: ${{ steps.acs.outputs.delta }}"
+ echo "new errors: ${{ steps.acs.outputs.new-errors }}"
+```
+
+The Action emits outputs before returning its final regression status. Use `if: always()` when a downstream step must consume metrics even after the gate intentionally fails.
+
+## Design principles
+
+1. **Regression-first.** Existing repositories do not have to become perfect before CI becomes useful.
+2. **Baseline-governed policy.** A candidate cannot weaken the gate evaluating itself.
+3. **Auditable exceptions.** Suppressions need a reason and expiry, remain visible, and cannot self-authorize.
+4. **Local-first.** Repository content is not uploaded to a hosted analysis service, and automatic Git baseline detection does not fetch.
+5. **Explainable.** Scores map to stable rule IDs and visible findings; A 100 is never presented as semantic certification.
+6. **Conservative.** Prefer a missed warning over noisy fake certainty.
+7. **Zero runtime dependencies.** Python 3.10+ standard library only.
+
+## Roadmap
+
+- [x] deterministic 0–100 scoring
+- [x] baseline → candidate regression comparison
+- [x] Markdown PR / Step Summary report
+- [x] first-class reusable GitHub Action
+- [x] structured GitHub Action outputs
+- [x] SARIF output for GitHub code scanning
+- [x] Git-aware local diff without manual worktrees
+- [x] automatic local default-branch baseline detection
+- [x] baseline-governed repository policy
+- [x] safe one-command repository initialization
+- [x] repository integration doctor
+- [x] stable Rule Catalog and rule inspection
+- [x] reasoned / expiring suppressions
+- [x] JSON Schema + editor validation
+- [x] end-to-end behavior contract fixtures
+- [x] score-history artifact / badge workflow
+- [x] bounded nested `AGENTS.md` scope/override handling
+- [x] Codex `AGENTS.override.md` discovery / precedence
+- [x] copy-ready Cursor, Copilot, Gemini, and Claude Code templates
+- [x] adversarial score-contract audit and documented blind spots
+- [x] removal and exact directive-polarity regression checks
+- [x] installed-wheel end-to-end acceptance on Linux, Windows and macOS in CI
+- [x] source and installed-package gates before publication
+- [x] user guide, exit-code reference and troubleshooting
+- [x] versioned English core package with release notes and compatibility guidance
+- [x] optional Simplified and Traditional Chinese core documentation and README language switch
+- [x] unreleased Cursor activation and exact-directive availability comparison
+- [ ] optional semantic contradiction plugin
+
+See [release readiness and the localization sequence](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/release-readiness.md).
+Semantic extensions are optional; they are not a prerequisite for the core
+deterministic CI checker.
+
+The localized core overview, user guide and limitations are available separately;
+advanced references and research documents remain English. See the
+[translation scope and maintenance note](https://github.com/LE0-Lin/AgentConfigScore/blob/main/docs/translations.md).
diff --git a/docs/translations.md b/docs/translations.md
index 5bae9d9..67c684b 100644
--- a/docs/translations.md
+++ b/docs/translations.md
@@ -12,7 +12,7 @@ providing Chinese documentation.
| English source | 简体中文 | 繁體中文 | Scope |
|---|---|---|---|
-| [README](../README.md) | [Overview](../README.simplified.md) | [Overview](../README.traditional.md) | Localized core overview, not the entire long English reference |
+| [README](../README.md) | [Overview](../README.simplified.md) | [Overview](../README.traditional.md) | Core overview and released/source distinction; detailed reference remains English |
| [User guide](user-guide.md) | [Guide](simplified/user-guide.md) | [Guide](traditional/user-guide.md) | Core user journey, all executable examples, exit codes and troubleshooting |
| [Limitations](limitations.md) | [Limits](simplified/limitations.md) | [Limits](traditional/limitations.md) | Core score contract, rule limits and unestablished accuracy; historic table/manual links stay in English |
@@ -170,6 +170,15 @@ guide examples are identical in all three languages. Detailed comparison/CI
guidance and four synthetic controls remain English references. No application
documents, published package/Action refs or frozen evaluation data were changed.
+Also on 2026-11-04, built on `1580df39946523a2ca6203d819625b1e22084332`, the
+three repository overviews were aligned around instruction-change review,
+baseline-governed checks and a clearly unreleased Cursor attachment example.
+Both Chinese variants retain identical executable/config/workflow examples.
+The current five-scan/one-expected-rejection corpus status replaces the ambiguous
+historic Reaparr A 100 summary. Detailed policy, CLI and integration material
+moved from the English homepage into [the English reference](reference.md).
+Runtime behavior, published artifacts, Action refs and frozen evidence are unchanged.
+
When an English source page changes, review both variants together and record
the new source revision here. Preserve executable examples, rule IDs and JSON
keys verbatim. Keep the score limitations and failure/exit semantics aligned;